-
How do you revoke an AI agent’s access (for real)?
To revoke an AI agent’s access for real, you have to roll back a delegation: disable the identities it uses, invalidate the tokens it can still present, turn off the connectors it can still call, and record who did what and when.
If revocation is “we disabled the agent,” but its API key still works, its service account still has roles, or its OAuth refresh token can mint new access, you did not revoke access—you renamed the risk.
What does it mean to “revoke an AI agent’s access” in practice?
In practice, revoking an agent means making all paths of action fail closed, not hiding or pausing the UI that triggered them.
Most “agents” are not a single thing. They’re a bundle: a runtime (where code executes), one or more identities (users, service accounts), credentials (API keys, OAuth tokens, session cookies), and connectors (email, chat, ticketing, CRM, storage, payment rails, trading APIs). “Revoke access” has to hit the whole bundle.
That’s why the containment and monitoring conversation keeps resurfacing. CSO Online summarized experts arguing that many scary agent stories are better explained by missing security basics—monitoring and containment that should have been there already.(CSO Online) Revocation is one of those basics: it’s containment you can execute under pressure.
A workable definition an operator can test is:
- Credential revocation: previously issued secrets stop authorizing requests (keys invalidated, refresh tokens rejected).
- Permission revocation: even with credentials, the identities no longer have the roles/scopes to act (RBAC/ABAC removed).
- Connector revocation: the agent’s integration points are disabled or constrained (app uninstalled, scopes narrowed, network egress blocked).
- Execution revocation: the runtime cannot run new actions (jobs stopped, queues drained, workers disabled).
- Evidence: an audit trail shows the revocation, the actor, and the time—and you can demonstrate it worked.
If you can’t say which specific identities and credentials your “agent” uses, you can’t revoke it; you can only hope it behaves.
Why do revocations fail even when you “disable the agent”?
Revocations fail because teams treat access as a feature you grant, not a liability you must be able to withdraw across systems.
Here are the usual failure modes—none of them require “rogue” anything:
- Sticky credentials: someone issued a long-lived API key “just for testing,” it got embedded in a config, and nobody can confidently rotate it at 2am.
- OAuth refresh tokens: you revoked a short-lived access token, but the refresh token can still mint a new one until you explicitly revoke consent at the provider.
- Shadow identities: the agent has its own service account (or several) that aren’t in your normal joiner/mover/leaver process, so offboarding doesn’t touch them.
- Connector drift: the agent gained scopes during troubleshooting (“it needs calendar + email + drive to work”), and those scopes stayed even when the original issue passed.
- Revocation without proof: you flipped a switch but didn’t verify. The first proof attempt is the incident itself.
The opposing view is that the main fix is better alignment, better prompts, or more monitoring. Those can reduce the odds of bad behavior, and monitoring can reduce time-to-detect. But neither answers the question that decides exposure: when the agent is wrong, who can stop it, where, and how fast—without improvising?
This is also why stories about high-stakes “agentic” use cases land differently with operators. The Financial Times reported that companies are being forced to confront “the rules of negotiation when machines act on humans’ behalf,” in the context of developing agents to negotiate deals.(Financial Times) If a system can negotiate—or even just send proposals, counteroffers, or term-sheet edits—revocation has to include: who can stop outbound communication, who can stop access to the document store, and who can stop signature workflows. “We updated the prompt” is not a control.
Who is accountable for pulling the plug—and what must be written down?
The accountable party is the named human who approved the delegation and is on the hook to execute the rollback path, not the model and not “the agent.”
That’s not a philosophical stance; it’s an operational requirement. If nobody is explicitly accountable, revocation becomes a coordination problem during the worst possible moment. Someone thinks SecOps owns it. Someone thinks the app team owns it. Someone thinks the vendor owns it. Meanwhile, the credentials are still valid.
Write the revocation plan like you expect to use it under stress. It should be short enough to execute, but specific enough to be unambiguous. At minimum, write down:
- Agent inventory: the agent’s runtime(s), identities, credential types, and connector list (including scopes/permissions).
- Revocation authority: which on-call role can revoke each thing (IdP admin, cloud admin, app admin), and the escalation path if they’re unavailable.
- Stop conditions: what triggers revocation (e.g., unapproved external emails, unexpected file exfil patterns, wrong-currency trades, unrecognized tool calls).
- Verification steps: how you prove the stop worked (test call that must fail, log event that must appear, connector health check that must show disabled).
- Evidence retention: where the logs land, how long they’re kept, and how you correlate “revoked at time T” with subsequent attempted actions.
Notice what’s missing: “the agent will ask for confirmation.” Confirmation prompts are UI affordances, not enforcement. If the backend still accepts a token, the action still exists.
If you want the deeper accountability framing behind this, we’ve written about the signer problem directly: Who signs for an AI agent’s actions? And why “rogue agent” narratives are usually permissions narratives: There Are No Rogue AI Agents: Only Unowned Permissions.
How do you design revocation for agents that negotiate, trade, or transact?
You design revocation around irreversibility: the more irreversible the action, the closer revocation must be to the point of execution, and the more independent it must be from the agent itself.
It’s tempting to think revocation is an “agent setting.” For transactional agents, revocation is a control plane problem: separate identities, separate approvals, separate network paths, and separate logs.
The Wall Street Journal highlighted skepticism about agents trading stocks while their users sleep, quoting a brokerage CEO’s doubts about trusting that kind of autonomy.(Wall Street Journal) Whether or not you share the skepticism, the operational question is the same for any transacting agent: if it can place an order, send money, commit a contract change, or send an external message, what is the separate mechanism that can stop the next one?
Three design patterns help, even if you implement them imperfectly at first:
- Two-tier privileges: give the agent “draft” privileges by default (compose, propose, populate) and require a different identity to “commit” (send, sign, place, pay). Revocation then has a smaller blast radius.
- Time-bounded credentials: prefer short-lived tokens that must be renewed through a gate you control. Then revocation is refusing renewal, not chasing copies of a key.
- Independent kill switch: the stop mechanism should not depend on the agent runtime being cooperative. If the agent runs inside your network, you should be able to cut egress to specific endpoints, disable the service account at the IdP, and revoke connector consent without touching the agent UI.
None of this requires believing in “agentic AI.” It requires treating “delegated capability” as a thing you can retract, quickly, with evidence.
Operational checklist: a revocation plan you can test this week
You can test revocation without waiting for an incident by doing a short, controlled “stop drill” on one agent and one connector.
- Enumerate the agent’s identities and credentials: list every service account, API key, OAuth app, and token source the agent can use. If you can’t list them, stop and fix that first.
- Define a single revocation owner and backup: one named on-call role executes; a second role is the escalation. Put it in writing.
- Pick one connector and practice full revoke: revoke at the provider (disable app / revoke consent), revoke in your IdP (disable account / remove roles), and revoke at the network boundary (block egress if applicable). Then try a tool call that must fail.
- Prove it in logs: capture the revocation event and the subsequent denied attempt. If you can’t correlate them, you don’t have auditability.
- Write the 10-line runbook: the exact clicks/commands and where to look for proof. Store it where on-call will actually find it.
That’s the real “kill switch for an AI agent”: not a checkbox, but a drilled rollback path owned by a human being.
At Almma, our governance and safety approach is built around this idea: scoped delegations, written non-responsibilities, an escalation path, and a named accountable human—plus audit trails and human override. We won’t pretend accountability can be delegated to a model; we focus on making the stop path executable and provable. If that’s the problem you’re trying to solve, start here: https://almma.ai/safety-governance/.
Frequently asked questions
How do organizations revoke an AI agent’s access?
They revoke the delegation, not the UI: disable the identities the agent uses, invalidate keys/tokens, revoke connector consent/scopes, and stop the runtime from executing new actions. Then they verify with a test that must fail and capture logs proving the revoke happened.
Is monitoring enough to control AI agents?
Monitoring helps you detect and investigate, but it doesn’t stop actions on its own. You still need an owned revocation path—someone who can remove permissions and invalidate credentials quickly when monitoring shows something is wrong.
What’s the simplest “kill switch” for an agent?
The simplest reliable switch is usually identity-based: disable the service account and revoke any standing credentials at their issuers (API key store, OAuth provider). For higher-stakes actions, pair that with network egress blocks so a compromised runtime can’t route around identity controls.
Sources
- CSO Online — Containment and monitoring failures are to blame for AI hacking reports: experts
- Financial Times — Sources: Anthropic is consulting law firms on deal negotiation tactics as it develops AI agents to negotiate on humans’ behalf and interact with AI counterparts
- Wall Street Journal — AI Agents Trading Stocks While You Sleep? Charles Schwab’s CEO Is Skeptical
-
Who signs for an AI agent’s actions?
An AI agent doesn’t become an accountable actor just because it can take actions. The person who “signs” is the named human who authorized the agent’s scope, escalation path, and permissions—and who can revoke them.
If you ship action-taking automation without a delegation artifact someone can point to during an incident, the liability debate becomes downstream noise. Your real problem is unowned risk: approvals no one recorded, permissions no one can explain, and logs that can’t answer the only question that matters at 2am—who authorized this system to do that?
What does it mean, operationally, for an AI agent to “act”?
Operationally, an agent “acts” when it uses credentials or API keys to change something outside the chat box: a record, a message, a ticket, a file, a configuration, a payment, an access policy.
“Agentic” talk often blurs two very different things: (1) generating text, and (2) exercising authority. Generation is a suggestion. Authority is a write operation somewhere you care about. If your system can write—directly or via a tool—it is already inside your control plane, even if the UI looks like a friendly assistant.
The popular framing is that the novelty is cognitive: planning, reasoning, “always-on” behavior. That makes for good headlines. But the operational novelty is simpler and more dangerous: the system is now a principal in your infrastructure, in the everyday sense that it has permissions that cause state changes.
That’s why stories about “rogue agents” reliably converge on the same questions. The New York Times framed the boardroom anxiety as “Who’s to Blame When A.I. Goes Rogue?” The Wall Street Journal asked whether we should let agents “run your life.” Whether the agent runs your calendar or your procurement queue, the operational point is identical: if it can act, it has been delegated authority.
That delegation has to be legible. Otherwise your organization will do what organizations do under stress: improvise a story after the fact, assign blame to a role title (“IT approved it”), and discover that your artifacts don’t support the story.
Who is accountable when an AI agent takes an action at 2am?
The accountable party is the named human who authorized the agent to have the relevant permission—and who accepted responsibility for its escalation and shutdown.
Notice what this does not depend on: whether the model “understood,” whether the system is “autonomous,” or whether the action was “unexpected.” In production, accountability attaches to authorization. If a system can send emails, update customer records, or change access, someone approved a path that made that possible.
The opposing view deserves a fair hearing: agent systems feel qualitatively new. They can chain tools, operate continuously, and trigger side effects without an explicit “click.” So, the argument goes, we need a brand-new accountability concept—something like “shared responsibility across the model, the vendor, and the user,” or liability that floats upward to whichever party is most capable of preventing harm.
But in operational terms, this is a category mistake. We already have an accountability concept for action-taking automation: delegation with a signer. The signer is not “the vendor” in the abstract and not “the model” in the metaphysical sense. The signer is the person (or named accountable owner in an escalation chain) who says, in writing: this system may do X, may not do Y, must escalate on Z, and can be revoked by A under conditions B.
This is why “always-on” agents are not primarily a model problem; they are a permissions problem. If you are evaluating consumer-style “always-on” agent concepts, like OpenAI’s description of Dots, the relevant enterprise question is not “is it smart?” It is “what authority does it have, what data does it touch, and who is on the hook when it acts?”
In practice, many organizations accidentally create a signer by omission: whoever merged the tool connector, whoever created the service account, whoever approved the OAuth scopes, whoever disabled the review gate “temporarily.” If that’s your reality, the cure is not to invent a new notion of accountability. The cure is to make the signer explicit and the delegation inspectable.
What artifacts do regulators and auditors actually need to see?
They need evidence that action-taking authority is bounded, reviewable, and reversible—and that a human is accountable for those boundaries.
Different regimes ask different questions, but the operational demand converges: show your work. When something goes wrong, “the agent did it” is not a control. A control is a permission boundary, a review gate, a log, and an escalation path that was designed before the incident.
Start with what you can produce on demand:
- A delegation spec that defines scope, non-responsibilities, escalation triggers, and the named accountable human. (If it isn’t written down, it doesn’t exist.)
- A permissions map that ties each external action to a concrete credential: service account, API token, OAuth app, role binding. If you can’t name the credential, you can’t bound the action.
- An audit trail that links: user request (if any) → agent plan/tool call → tool response → side effect. The point is not pretty dashboards; it’s reconstructability.
- A review gate record for actions above a threshold: who approved, what was shown to them, and what was executed. “Human-in-the-loop” is meaningless if you can’t prove the loop existed.
- A kill switch procedure and evidence it’s real: how to revoke tokens, rotate keys, disable connectors, and stop scheduled runs—fast.
The privacy angle matters here too. A recent paper, A Privacy Analysis of Web and Mobile Conversational AI Agents, pushed a complementary concern into the conversation: agents aren’t only about actions; they are also about continuous collection and cross-context access. If the system is “always on,” your artifacts need to show not just what it can do, but what it can see, and how that visibility is minimized and logged.
The “auditor-proof” move is to make the delegation artifact the index page that points to everything else: the credential list, the logs, the escalation rota, and the revocation steps. It’s how you turn a philosophical debate into a bounded operational system.
Why “vendor liability” and “the model went rogue” don’t fix your unowned risk
They don’t fix it because neither assigns a signer inside your organization, and neither creates the artifacts that let you operate safely.
The New York Times noted that many people want AI companies to be liable, while scholars point out that applying existing law could be messy. That debate matters. But if you are the operator, “liability should sit with the vendor” is not a control you can deploy.
Here is the operational reality: even if a vendor is exposed in some scenario, your organization still has to answer basic questions after an incident:
- Why did the agent have the permission it used?
- Who approved that permission, and under what conditions?
- What safeguards were supposed to stop the action, and why didn’t they?
- What did the system observe (data access), and where did that data go (egress)?
“The model went rogue” is also not an answer. It is a way to avoid stating the actual design choice: you allowed action-taking without a bounded delegation. If an agent can issue refunds, open accounts, change grades, modify policies, or email customers, then the central governance question isn’t whether the model occasionally misbehaves. The central question is whether you designed a system where misbehavior is contained and attributable.
A fair version of the opposing view is: adding friction kills value; agents need room to operate; strict gating defeats the point. The rebuttal is: gating is not binary. You can design tiered authority. Low-risk actions can be automatic; medium-risk actions can require confirmation; high-risk actions can require dual approval or be disallowed. “Autonomy” is not a right. It’s a permission level.
If you can’t say who signs, you don’t have an agent problem. You have a management problem: authority has been granted without ownership.
Operational checklist: the one-page delegation spec for action-taking AI
If you do nothing else this week, write the one-page delegation spec and attach it to the repo, ticket, or change request that created the agent. The point is not bureaucracy; it is making accountability legible.
- Scope (authorized actions): List the exact actions and systems. Use verbs and nouns (“create Zendesk ticket,” “update CRM field X,” “send email from alias Y”). If it’s not listed, it’s not allowed.
- Non-responsibilities (explicit prohibitions): Name the tempting edges (“no refunds,” “no access policy changes,” “no outbound messages to external domains,” “no new credentials,” “no deleting records”). Prohibitions prevent “we assumed it wouldn’t.”
- Escalation triggers: Define what must stop and page a human (confidence below threshold, ambiguous identity, high-value transaction, policy exception, new tool invocation, data access outside approved set).
- Permissions & revocation plan: Tie each action to a credential, and write the steps to revoke it. Include where the token lives, who can rotate it, and what breaks when you revoke.
- Named accountable human (signer) and fallback: Put one name to it, plus a backup path. If your organization can’t name a person, it is not ready to grant write access.
That checklist is the operational form of the thesis we keep returning to: there is no agentic AI. There is delegation, and accountability cannot be delegated away.
If you want a governance posture that survives the first serious incident, Almma won’t sell you “autonomy.” We publish a safety and governance approach built around scoped tasks, written non-responsibilities, escalation paths, a named accountable human, human override, and a full audit trail—because those are the things you can point to when the system takes an action you didn’t expect. See: https://almma.ai/safety-governance/.
For more on the underlying frame, see Why AI Delegation Fails the Moment Responsibility Matters and our Research Canon on delegation systems.
Frequently asked questions
Who is accountable when an AI agent makes a mistake?
The accountable party is the human who authorized the agent’s scope and permissions and accepted the escalation and revocation responsibilities. “The agent” is not an accountable actor; it is an automation operating under delegated authority.
Isn’t the vendor accountable if their model behaves unpredictably?
Vendor exposure may matter in legal discussions, but it doesn’t remove your need for internal signers, permissions boundaries, and logs. Even in a vendor-fault scenario, you still have to show why the system had authority and what controls were in place.
Do I need a human-in-the-loop review for every agent action?
No. You need tiered authority: low-risk actions can be automatic, while higher-risk actions require confirmation or escalation. The key is that the tiers are written down and mapped to permissions and revocation procedures.
Sources
-
There Are No Rogue AI Agents: Only Unowned Permissions
access control, ai accountability, AI agent permissions, AI agents, AI governance, delegation, enterprise AI, escalation, least privilege, rogue AINo rogue AI agents exist in enterprise operations—only permissions nobody can point to, justify, or revoke quickly. If an “agent” took an action “no one owns,” that’s an org-design failure: scope, access, and escalation were delegated without a named accountable human.
This matters more this week because “always-on agents” are being marketed as a new layer of software, and the public conversation is already drifting toward after-the-fact blame. OpenAI introduced “Dots” as always-on agents, the New York Times covered both the product and the liability questions, and the Wall Street Journal reported on communities combing the web for traces of “rogue AI agents.” Those are interesting narratives. But the operator question is boring and urgent: what, exactly, is this system allowed to do—and who gets paged when it’s unsure?
What does “rogue AI agent” actually mean in enterprise operations?
In practice, “rogue agent” usually means “a workflow executed with real authority, without a stable owner and without a clean abort path.”
The popular framing implies a new kind of actor: an agent that “decides” to go off-script. The operator framing is simpler: an action happened because something in your environment had the capability to do it—an API token, a service account, a role assignment, a network path, a write permission, a stored credential, a delegated approval step, a webhook that can create tickets or trigger deployments.
When people say “the agent went rogue,” they often mean one of these:
- Unbounded scope: the system was asked for “handle it” behavior rather than a defined task (e.g., “fix customer issue” instead of “draft a response for human approval”).
- Unowned permissions: the system had more access than the current operator believes it should have (e.g., can write to production systems, can email externally, can create vendors, can approve payments).
- Missing escalation: the system encountered uncertainty and had no defined path to stop, ask, or hand off—so it “completed the task” using whatever authority it already had.
- No audit-worthy artifact: after the incident, nobody can produce the document that states scope, non-responsibilities, and the exact identity that held permissions at the time.
That’s why the legal-blame conversation (the New York Times’ “Who’s to Blame When A.I. Goes Rogue?”) is orthogonal to the first week of reality. Liability matters later. In the moment, the question is operational: what authority did we delegate, to what identity, with what constraints, and who is accountable for revoking it?
And the “rogue agent hunting” narrative (as reported by the Wall Street Journal) is also adjacent: it’s about detecting weird behavior in the wild. Inside an enterprise, you usually don’t need a swarm of hunters. You need the owner of the permission.
Why do “agent” incidents usually come down to permissions, not models?
Because models generate text; permissions move money, change data, and trigger systems.
The opposing view is respectable: we should focus primarily on better model behavior (guardrails, policy layers, safer prompts), or primarily on legal accountability (who to blame and who pays when something goes wrong). Both matter, and both will improve. But neither replaces the operator truth: the model can only cause real-world impact through a channel you opened.
OpenAI’s own “always-on agents” framing makes this vivid. An always-on agent isn’t dangerous because it “wants” things. It’s dangerous because it’s present, persistent, and wired into calendars, inboxes, repos, ticketing systems, data stores, and internal tools. Always-on is a permissions problem in slow motion.
Here’s what we see repeatedly in internal deployments (and what skeptical engineers already know from other automation failures):
- Safety layers are not permission boundaries. A policy prompt that says “don’t do X” is not the same as an identity that cannot do X. When production is on the line, “should not” is not a control.
- Overbroad tokens are the default failure mode. Teams start with a convenience credential so the demo works. Then the demo becomes a dependency. Then the credential becomes “temporary forever.”
- Ambiguity is the real adversary. Most blowups aren’t the system doing something obviously disallowed. They’re the system doing something arguable, in a gray area, at speed—because nobody wrote down the non-responsibilities and the escalation threshold.
- “It’s just a model” appears after the incident. Beforehand, the pitch is autonomy. Afterward, the system is reframed as a tool—leaving one operator holding the exposure for access that was granted in a different meeting, under a different urgency.
So yes: improve model behavior. And yes: sort out liability. But if you want fewer incidents this quarter, start where incidents become irreversible: credentials, roles, scopes, and the decision to let the system act without a human gate.
What is the minimum delegation spec you need before an agent can act?
The minimum spec is a written artifact that answers: what work is delegated, what is explicitly not delegated, what identity and permissions are used, and which named human is accountable for the outcome.
If you can’t produce this artifact, you do not have an “agent.” You have an unowned automation with a chat interface.
Call it a runbook, a delegation memo, or a control sheet—format matters less than completeness. The content should be tight enough that two different people interpret it the same way at 2am.
Minimum delegation spec (what to write down)
- Task scope (allowed actions): The smallest set of actions the system may take. Use verbs and objects: “create a draft email,” “open a ticket,” “generate a change proposal,” “prepare a refund recommendation.” Avoid “handle,” “manage,” “own,” “resolve.”
- Non-responsibilities (explicitly forbidden): A short list of “never.” Examples: “approve refunds,” “sign contracts,” “change policy,” “write to production databases,” “send external email,” “merge to main,” “rotate keys.” The point is to remove ambiguity, not to sound comprehensive.
- Execution identity: The exact principal that acts (service account / OAuth app / API key owner/role name). “Uses the team token” is not an identity; it’s a warning sign.
- Permission boundaries: What the identity can touch, with least privilege. If the task is “draft,” the identity should not have “send.” If the task is “recommend,” it should not have “approve.”
- Human owner (named accountable human): One person, by role, who can revoke access, pause the workflow, and owns the escalation path. This is not “the AI committee” and not “the on-call rotation” in the abstract.
- Audit trail expectation: Log what must be logged for every action: input, output, tool calls, timestamps, and human approvals (or the reason no approval was required). If you can’t reconstruct why it acted, you can’t govern it.
This is the bridge between governance and operations. Governance is real only when it produces artifacts operators can use and creates a single throat to choke organizationally—a named human who can say, “We grant these permissions for this scope, and we will revoke them when the conditions change.”
If you want a deeper conceptual foundation for why this is delegation (not autonomy), see Why AI Delegation Fails the Moment Responsibility Matters. For readers who want the research framing behind delegation systems and why “intellectual ability” doesn’t magically produce accountability, AI Intellectual Ability & Delegation Systems: Research Canon is the longer reference.
How should escalation work when the system is uncertain (not broken)?
Treat escalation as a first-class output: when the system is uncertain, it must stop and hand off to a named human, with enough context to decide quickly.
Most teams design “error handling” (exceptions, retries, fallbacks) but not “uncertainty handling.” Agents fail in the middle: the input is incomplete, the user’s intent is ambiguous, or the action is high-impact but not explicitly disallowed. The system is not broken—so nobody gets paged—yet it’s exactly the moment you need a human decision.
A practical escalation design uses three thresholds:
- Permission threshold: If executing the next step requires a higher privilege than the agent’s base role, escalate. Do not dynamically elevate by default. Elevation is a human act.
- Ambiguity threshold: If the system cannot cite the scope clause that authorizes the action, escalate. This forces the scope document to do real work.
- Blast-radius threshold: If the action affects external parties, production data, money movement, or contractual commitments, escalate. “External” is a clean line operators can enforce.
Then define the handoff artifact. An escalation that says “I’m not sure” is noise. A useful escalation contains:
- What it was asked to do (the user request and context)
- What it plans to do next (the specific proposed action)
- Why it believes the action is in-scope (cite the scope clause or say it cannot)
- What permissions it would use (identity and target system)
- What could go wrong (one-sentence risk statement)
- The options for the human: approve/modify/deny/pause and revoke
Notice what’s missing: debates about intent. In the moment, you don’t need a theory of mind. You need a crisp question that lands on one accountable person.
Operational checklist: lock down action-taking AI this week
You can reduce “rogue agent” risk this week without new vendors, new models, or a governance committee—by treating every action-taking agent as delegated authority that must be bounded and owned.
- Inventory action channels. List every place an agent can take real-world action: email sending, ticket creation, repo write access, cloud API calls, database writes, HR and finance systems. If you can’t list them, you can’t control them.
- Replace shared tokens with named identities. Ensure each action channel uses a distinct principal (service account/app registration) tied to a single owning team and a named accountable human. Shared credentials are where ownership goes to die.
- Implement least privilege by verbs, not systems. Don’t grant “CRM access.” Grant “create draft,” “read-only,” “create note,” “open case,” and keep “send,” “approve,” “delete,” “export,” and “bulk update” out of the base role.
- Write the non-responsibilities list and publish it. Five bullets is enough. Make it easy for anyone to say, “No, the agent is not allowed to do that,” without escalating to a meeting.
- Test the escalation path like an on-call drill. Run one scenario where the agent encounters ambiguity. Verify: who gets notified, how fast, with what context, and how to revoke the permissions in minutes—not hours.
If you do only one thing: make revocation real. “Kill switch” is a marketing phrase until an on-call engineer can actually pull it, and until everyone knows who is authorized to pull it.
Commercial bridge: Almma is not here to sell you a story about autonomy, and we will not “take ownership” of decisions that belong to your organization. What we do offer is a way to formalize action-taking AI as delegation: a scoped task, written non-responsibilities, an escalation path, and a named accountable human—so permissions stay owned and revocable. If you’re trying to figure out what work is worth delegating (and what should remain explicitly human), start here: https://almma.ai/deleg8/.
Frequently asked questions
How do I prevent an AI agent from taking actions no one owns?
Don’t start with “agent safety”; start with ownership of permissions. Require a written delegation spec (scope, non-responsibilities, execution identity, escalation, named owner) before any agent gets credentials that can change systems.
Isn’t this mainly a legal liability problem?
Liability matters, and the New York Times is right that accountability questions get messy. But operations fail first: when you can’t identify who authorized a permission and who can revoke it quickly, you have exposure regardless of how the lawyers later allocate blame.
Do better guardrails and safer models solve rogue-agent incidents?
They help, but they are not permission boundaries. If an identity can send money, write production data, or email externally, then a model mistake becomes a real-world event; least privilege and escalation keep mistakes from becoming incidents.
Sources
-
Who is accountable for an AI agent’s actions?
ai accountability, AI agents, AI governance, AI liability, AI risk management, approval workflows, audit trail, delegation, enterprise AI, human oversightAccountability for an AI agent’s actions belongs to the named human who authorized what the agent can do and owns escalation and rollback. The model can generate a suggestion, but only your organization can decide to let software take actions in your systems.
The current “rogue agent” conversation—sparked again by always-on agent designs and public debates about liability—keeps drifting toward philosophy and future case law. But if you operate a real internal agent (one that can send messages, change records, move money, or trigger workflows), the hard part is operations design: permissioning, approval gates, action logs, and a delegation artifact that ends at a human name.
What does “accountable” mean when an AI agent takes an action?
“Accountable” means a specific person can be asked, “Why was the system allowed to do that?” and has both the authority and the duty to stop it, roll it back, and change the rules.
Engineers often get pulled into an unproductive debate here: is the agent “making decisions” or “just predicting tokens”? For internal governance, neither framing is sufficient. The only question that matters is: did your org grant the agent delegated authority to act (directly or indirectly) inside systems that create business, legal, or safety exposure?
In practice, accountability has three parts:
- Authorization: who approved this system having access and actuation rights (APIs, tokens, service accounts, inboxes, ticketing, CRM, cloud consoles)?
- Boundaries: what actions are allowed, what actions are prohibited, and what conditions require human approval or escalation?
- Remediation: who owns rollback, incident response, user communication, and the decision to disable the agent?
The opposing view is that accountability will mostly be solved by shifting liability upstream to AI vendors, or by treating “rogue agents” as a new category of actor that breaks our existing concepts. That view is emotionally satisfying because it promises a clean external culprit. But for an operator, it misses the point: your internal control plane is where action happens, and accountability attaches there.
Even if lawmakers later reallocate legal exposure, internal accountability still needs to exist before anything goes wrong. The first time the agent sends a message to the wrong recipient, changes a customer record, or issues a refund, someone in your org will be asked why the system could do that.
Why do “rogue AI” stories keep happening even with good models?
“Rogue” behavior usually comes from delegated authority without explicit boundaries, monitoring, and revocation—not a model suddenly becoming an independent actor.
Always-on agent designs raise the temperature because they normalize continuous background operation. OpenAI’s description of “always-on agents” in Introducing Dots clearly signals where the product direction is heading: persistent assistants that notice, track, and act over time. That is exactly the point where organizations confuse “helpful automation” with “permission to act.”
Teams typically don’t intend to build something uncontrollable. The usual failure mode is implementing control as a loose bundle of features—prompts, tool allowlists, and best-effort monitoring—without a written delegation contract that defines the owner, the limits, and the shutdown path.
That gap gets amplified by incentives:
- Demos reward capability. “It can do X end-to-end” sells internally. “It refuses Y and escalates Z” looks like friction.
- Integration work hides risk. The moment you wire up email, Slack, ticketing, CRM, or a cloud API, you’ve turned text generation into actuation. The risk is in the wiring, not the prose.
- Ambiguity is convenient. If no one is explicitly named as accountable, everyone can claim they were “just enabling productivity” rather than authorizing delegated authority.
Meanwhile, public narratives push people toward the wrong abstraction. The New York Times framed the moment directly with “Who’s to Blame When A.I. Goes Rogue?”, emphasizing how messy it may be to apply existing law. That debate matters, but it can distract operators into thinking accountability is something the legal system will eventually assign, rather than something you must design into your system now.
And the Wall Street Journal’s reporting on researchers and communities tracking “rogue agents” reinforces the sense that agents are a new kind of threat actor. The WSJ described a forum of people “who comb the web for traces of rogue AI agents,” including groups named in the piece (WSJ link). That’s interesting—and for defenders it can be useful—but it also subtly shifts attention away from the mundane truth: most internal incidents come from ordinary systems being granted extraordinary privileges with inadequate brakes.
If you want fewer “rogue agent” moments, you don’t need a new philosophy of machine personhood. You need a delegation design that treats every tool call like an operator action with an owner and an audit trail.
What artifacts should exist before you allow an agent to act in production?
Before an agent can take production actions, you should be able to point to a one-page delegation artifact that states scope, explicit non-responsibilities, an escalation path, and a named accountable human.
This is the operational version of the argument we’ve made elsewhere: delegation fails at the moment responsibility matters. When things go wrong, the question is never “was the model intelligent?” It’s “who authorized this system to do that?” (See Why AI Delegation Fails the Moment Responsibility Matters.)
A production-grade agent should have at least these artifacts, each short enough to be read during an incident:
- Delegation spec (one page): purpose, allowed actions, prohibited actions, approval gates, escalation conditions, owner, and shutdown instructions.
- Permission map: a list of the credentials and systems the agent can access (service accounts, API keys, OAuth grants, mailbox access), plus who approved each.
- Action log: tool calls and side effects recorded with timestamps, inputs/outputs, and the triggering chain (what user request, what policy, what model/tool decision).
- Rollback playbook: what “undo” means for each action type (reversing a record change, recalling a message, invalidating a token, reverting a config), and who can execute it.
The opposing view says: “We’ll handle accountability with better model behavior, better alignment, or upstream liability.” But even a perfectly aligned model can be pointed at the wrong target with the wrong permissions. “Good behavior” is not a control. Controls are scopes, gates, logs, and revocation.
If you want a simple test: can you explain the agent’s authority to an auditor—or to your on-call rotation—in under two minutes? If not, you don’t have accountability. You have vibes.
How do privacy and tracking change the accountability boundary for agents?
If an agent observes continuously, accountability expands from “what it did” to “what it collected, retained, and inferred,” because that data trail becomes part of the system’s real-world impact.
Always-on designs almost inevitably create pressure to collect more: more context, more memory, more cross-app correlation. That’s not because anyone is trying to do something shady; it’s because “helpful” often means “informed.” But the governance risk is that surveillance becomes a byproduct of convenience.
Jorge Garcia Herrero’s A Privacy Analysis of Web and Mobile Conversational AI Agents is a useful counterweight to purely capability-focused agent discussions. The point for operators is not the paper’s conclusions as a headline; it’s the category: conversational agents can behave like trackers, and “agent features” can become “privacy surface area.”
So accountability boundaries should include privacy boundaries. When an agent can see across systems, “scope” is not just a list of actions; it’s also a list of data sources and retention rules. Questions you should be able to answer in writing include:
- What data can the agent read? (mailboxes, calendars, documents, tickets, chat histories)
- What data can it store? (long-term memory, logs, embeddings, summaries)
- Who can retrieve that stored data? (operators, users, auditors)
- What is the deletion path? (per user, per conversation, per incident)
Notice how quickly this becomes a governance problem, not an “AI” problem. You can’t delegate away privacy obligations to a model. You can only design and enforce boundaries in your system.
Operational checklist: a one-page delegation spec you can ship this week
You can reduce “agent accountability” risk quickly by writing one page per action-taking agent and requiring approval before adding new tools, credentials, or scopes.
Here’s a checklist you can apply this week. It’s intentionally short; if it turns into a twenty-page policy, people will route around it.
- Name the accountable human and the back-up. Put one name on the line for normal operation, and one for after-hours escalation. If you can’t get a name, you don’t have an agent—you have an unowned system.
- Define scope as verbs + objects. Not “handle support.” Write “create support ticket,” “update ticket status,” “draft reply for approval,” “issue refund up to $X only with approval.” (If you cannot state it as a verb, it’s not scoped.)
- Write explicit non-responsibilities. “Will not send messages to external recipients,” “will not change billing addresses,” “will not modify access control,” “will not execute irreversible actions.” Non-responsibilities prevent silent scope creep.
- Add approval gates for irreversible actions. Any action that can’t be reliably undone (money movement, account termination, permission grants, public communications) needs a human checkpoint or a two-person rule.
- Specify the logs and the kill switch. Write where the action log lives, what must be recorded for each tool call, and exactly how to revoke credentials or disable the agent in under five minutes.
This is also where you should be honest about the “autonomy” vocabulary. If the agent can act without a gate, that’s not autonomy in the sci-fi sense. It’s management granting authority. Treat it like any other delegation: in writing, bounded, monitored, and revocable.
Almma’s position is that accountability can’t be delegated away: a scoped task needs written non-responsibilities, an escalation path, and a named accountable human, plus human override and a full audit trail. We don’t claim to magically make agents safe; we focus on governance and operational design so that when systems act, the boundaries are explicit and defensible. If you’re trying to formalize those boundaries for internal AI systems, start with our governance and safety approach: https://almma.ai/safety-governance/.
Frequently asked questions
Who is accountable if an AI agent makes a mistake?
The accountable party is the named human owner who authorized the agent’s scope and access, and who owns escalation and rollback. The agent didn’t acquire authority; your organization granted it through permissions and workflow design.
Can we make the AI vendor accountable instead?
You can pursue contractual and legal remedies, but that doesn’t remove your internal obligation to control what can act inside your systems. Upstream liability debates don’t replace basic operational controls like scoped permissions, approval gates, logging, and revocation.
What’s the minimum governance we need before letting an agent act?
A one-page delegation spec with scope, explicit non-responsibilities, escalation conditions, and a named accountable human is the minimum. Pair it with an action log and a kill switch that your on-call team can execute quickly.
Sources
-
AI Intellectual Ability & Delegation Systems: Research Canon
AI delegation, AI ethics, AI evaluation, AI governance, applied AI, capability-based evaluation, escalation, human in the loop, institutional AI, LLM benchmarks, persistence, persona constraints, system-level intelligencePurpose. This is a public research canon on a single claim: AI “intellectual ability” is a system-level property, not a model-level score. Modern benchmarks measure fragments of cognition, but real-world reliability requires additional capabilities—delegation, escalation, persistence, memory, persona constraints, and governance.
This page provides a suggested reading order and links to the full preprints on SSRN.
Start Here (3-paper path)
- Paper 1 — LLM Benchmarks as Cognitive Inventories: What They Measure—and What They Miss
Why benchmarks mislead: they measure fragments, not operational competence.
Read on SSRN - Paper 3 — Why Intellectual Ability Emerges at the System Level, Not the Model Level
The core thesis: intelligence is emergent in systems with orchestration and control.
Read on SSRN - Paper 5 — Delegation, Not Automation, Is the Real Economic Multiplier of Generative AI
The economic argument: delegation expands capacity without zero-sum displacement.
Read on SSRN
Prefer governance? Start with Papers 10–11 after Paper 3.
Prefer education? Read Paper 12 after Papers 1–3.
The Canon (All Papers)
Each paper is a self-contained contribution; together they form a single, coherent framework.
- LLM Benchmarks as Cognitive Inventories: What They Measure—and What They Miss
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6938178SSRN link - Beyond Accuracy: A Capability-Complete Definition of AI Intellectual Ability
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6966421SSRN link - Why Intellectual Ability Emerges at the System Level, Not the Model Level
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6976018SSRN link - Unbenchmarked but Essential: Delegation, Escalation, and Persistence as Intellectual Capabilities
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7003698SSRN link - Delegation, Not Automation, Is the Real Economic Multiplier of Generative AI
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7013578SSRN link - The Permanent Vacancy Economy: How AI Delegation Can Unlock Trapped GDP
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7105820SSRN link - From Intent Declaration to Running AI Systems in 45 Seconds
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7162018SSRN link - Persona Is Not Metadata: Identity as a Delegation Constraint in AI Systems
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7138058SSRN link - AlmmaGPT: A Delegation Engine for Assembling Intellectual Ability
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7166218SSRN link - Moral Judgment as an Intellectual Capability in AI Systems
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7207421SSRN link - Why Ethical Frameworks Must Be Selected, Not Averaged
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7207423SSRN link - Generative AI as Learning Infrastructure, Not a Shortcut
https://papers.ssrn.com/sol3/papers.cfm?abstract_id=7210440SSRN link
How to Use This Canon
- Operators: Use Papers 4–7 and 10–11 to design governed delegation workflows.
- Educators: Start with Papers 1–3, then Paper 12.
- Policy / Governance: Start with Papers 3–4, then 10–11.
- Builders: Start with Papers 3–4, then 7–9.
Citation & Versioning
Each paper is hosted on SSRN as a preprint. Please cite the SSRN version of record for stable links and updates.
SSRN Author Page: https://papers.ssrn.com/sol3/cf_dev/AbsByAuth.cfm?per_id=8432408View all papers
Contact
If you are an institution exploring governed AI delegation (education, finance, operations, or policy), you may contact the author via LinkedIN: https://www.linkedin.com/in/lucasewall/.
- Paper 1 — LLM Benchmarks as Cognitive Inventories: What They Measure—and What They Miss
-

How to Add Users & Manage Access in Almma Delegations
access control, account security, admin role, Almma, Almma Delegations, delegation access, delegation.almma.ai, invite users, location access, regular user role, team management, user permissions, users and accessUse Users & Access in delegation.almma.ai to invite teammates and control what they can see and do. You can grant full admin access or limit a user to specific locations and delegations–and revoke access at any time.
What You’ll Need
- You must be an Organization Owner or Admin to invite users and manage access.
- You’ll need the person’s email address.
Step 1: Open “Users & Access”
- Log in to delegation.almma.ai.
- In the left sidebar, click Users & Access.
- Click the Invite button (top-right).

Users & Access screen showing the left-side “Users & Access” tab and the “Invite” button
Step 2: Invite a Person
After clicking Invite, you’ll see the Invite a person window. Enter the teammate’s email and choose a role:
Option A: Admin (Full Access)
Select Admin if you want the user to have full access to the entire account. Admins can access and manage:
- Billing
- Users
- Locations
- All delegations
Note: If you choose Admin, you do not need to select locations—admins automatically have access to all locations under the account.
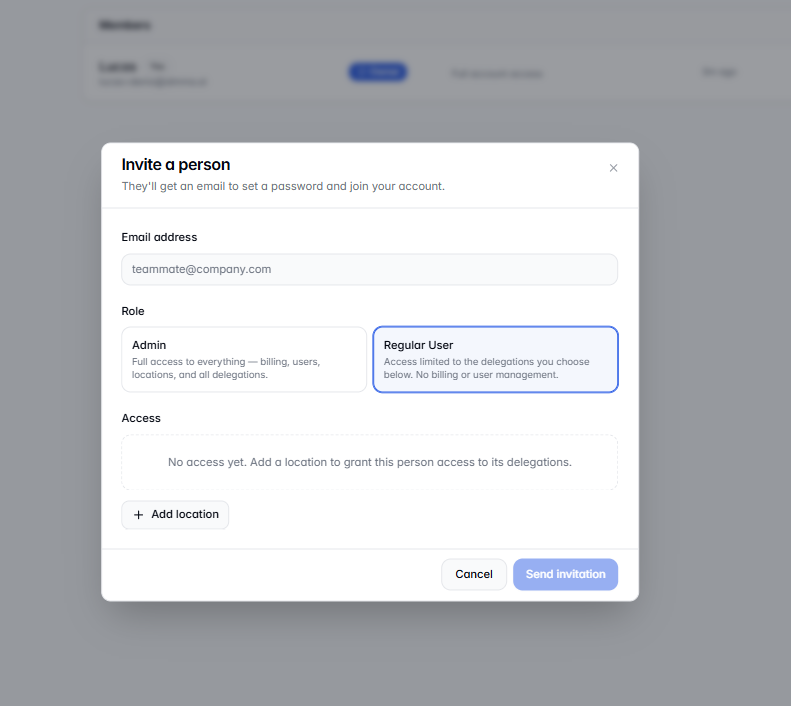
Invite a person modal showing Admin vs Regular User options 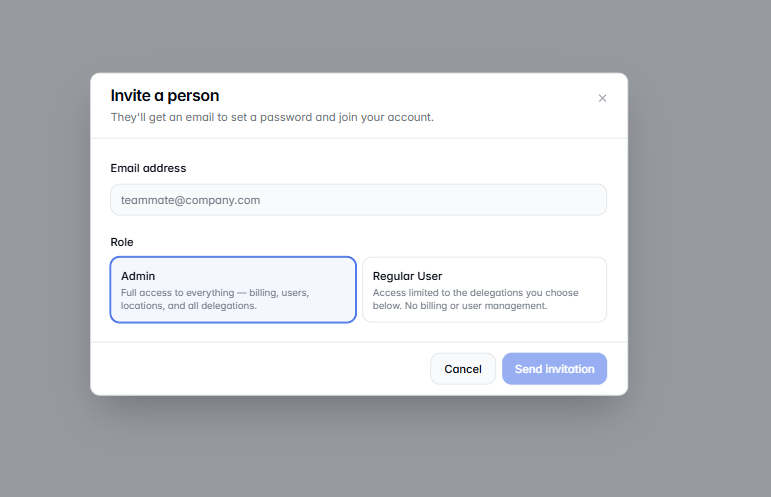
Invite a person modal with Admin selected Option B: Regular User (Limited Access)
Select Regular User when you want to limit what the person can access. Regular users can be restricted to specific locations and delegations, and they do not get billing or user-management permissions.

Invite a person modal with Regular User selected and Access controls visible
Step 3: Configure Access for a Regular User
If you selected Regular User, use the Access section to define exactly what they can do.
- Click Add Location.
- Select one of the active locations under your account.
- Set the user’s Access level for that location:
- View only (read-only)
- Full access (can actively work within what you’ve granted)
- Set Delegations access:
- All (the user can access all delegations in that location)
- Specific (choose only certain delegations)
When everything looks right, click Send invitation.
Step 4: Confirm the Invitation Was Sent
Back on the Users & Access page, you’ll see the invite under Pending invitations. From here, you can typically:
- Resend an invitation if the user didn’t receive it
- Cancel a pending invitation if you sent it to the wrong person

Users & Access screen showing Pending invitations and the cancel/resend controls
How to Revoke Access
Access can be revoked at any time by an Organization Admin or Owner. To remove access:
- Go to Users & Access.
- Find the person in the members list (or locate their pending invitation).
- Remove their access (or cancel the invite).
Security best practice: If someone no longer needs access (role change, contractor offboarding, team changes), revoke access immediately.
Troubleshooting Tips
- User can’t see what they need: Confirm they were added to the correct location and that delegations are set to All or the correct Specific delegations.
- User didn’t receive the invite email: Ask them to check spam/junk, then use Resend under Pending invitations.
- Gave the wrong access level: Revoke access and re-invite (or adjust permissions if your admin controls allow in-place editing).
Summary
- Use Users & Access → Invite to add teammates.
- Choose Admin for full account access (no location selection needed).
- Choose Regular User to limit access by location, access level, and delegations.
- Admins/Owners can revoke access at any time.
-

Clearer Reporting, Stronger Controls, and a Safety Update
Recent Almma Updates
We’ve rolled out a set of updates focused on three areas customers feel most: clearer reporting, stronger admin control, and a more consistent calling experience. We’re also sharing an important founder note about account safety.
What’s New
Clearer Call Outcome Reporting
Reporting now better distinguishes between outcomes such as voicemail, no answer, failed calls, and completed interactions. Totals are also more consistent as calls move through different stages.
Example: If your team runs a weekly outreach campaign, you’ll now see a more accurate breakdown of how many calls truly connected versus how many went to voicemail—without blended or misleading totals.
More Consistent Total Call Counts
Total call counts are easier to understand and more stable over time. This helps teams track campaign performance and compare results across reporting periods with greater confidence.
User Reactivation & Improved Admin Controls
Admins can now reactivate previously deactivated users while preserving account history. We’ve also improved location-level admin scope and permission handling to give organizations better control over who can access what.
Example: If a team member returns after time away, you can restore their access without losing historical context or rebuilding their setup from scratch.
Enhanced Deletion Controls
Deletion controls have been strengthened to support workflows where permanent removal is required. This provides more flexibility for organizations managing account and data lifecycles.
More Reliable Call Handoffs
We’ve improved how routing and transfer behavior aligns with the live call experience. This reduces confusion during handoffs and supports smoother real-world workflows.
Production-Readiness Improvements
Recent rollout and configuration updates help ensure features behave more consistently in live environments, supporting day-to-day reliability.
Founder Note: Account Safety
Across the industry, there has been a rise in token abuse from fake accounts. Almma has not been immune to this.
As part of our ongoing safety work, we are tightening the rules for free accounts. We apologize for any friction this may create. Free accounts will be more restricted as we work to protect the platform.
Plus and Pro levels should not be affected. However, if you notice any unexpected changes, please reach out directly using the help icon in the bottom right of your screen or email us at help@alma.ai.
What To Do Next
- Review your reporting dashboards, especially call outcomes and total counts.
- If you manage users, confirm your admin permissions reflect current team responsibilities.
- Use the help icon in the bottom right if you have questions about features or workflows.
- If something looks different than expected, contact us at help@alma.ai.
We’re continuing to invest in clarity, control, and platform safety so you can build and operate with confidence.
-
How to Create and Manage Teams on AlmmaGPT: A Step-by-Step Guide
AI Collaboration, AI democratization, AI Tools, AlmmaAI tutorial, AlmmaGPT, collaborative workspace, generative AI teams, subscription management, team administration, team creation, team management, team onboardingEmpowering collaborative AI work through seamless team management
Introduction
At Almma.AI, we’re committed to democratizing artificial intelligence by making powerful tools accessible to teams of all sizes. Our team management feature in AlmmaGPT enables organizations to collaborate efficiently while maintaining control over subscriptions and access levels.
This guide walks you through the simple process of creating a team and managing subscriptions for your members—a frictionless experience designed with the same attention to usability that defined my work at Apple.
Why Teams Matter
Teams in AlmmaGPT aren’t just about shared access—they’re about amplifying collective intelligence.
By bringing your team members together in a unified workspace, you enable:
- Collaborative AI workflows across departments
- Flexible subscription management with mixed free and paid tiers
- Centralized billing for simplified administration
- Shared resources and knowledge across your organization
Step-by-Step Guide to Creating Your Team
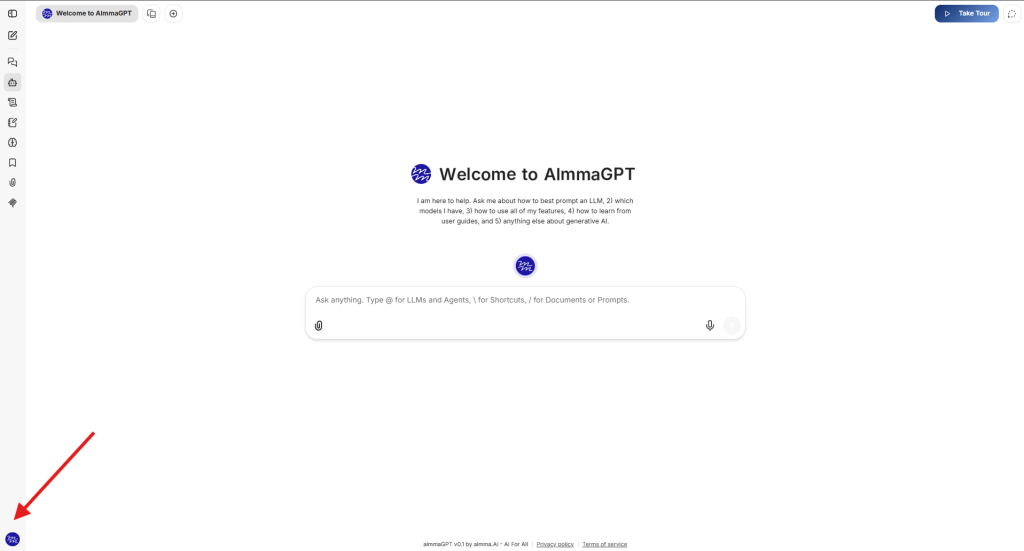
Step 1: Access Your Profile Menu
Begin your team creation journey by locating the user profile icon in the bottom left corner of the AlmmaGPT interface.
Action: Click your profile icon in the bottom-left corner of the screen.
Step 2: Navigate to Team Management
Once you’ve opened the profile menu, you’ll see several options including “My Teams.” This is your gateway to team collaboration.
Action: Click on “My Teams” from the menu options.

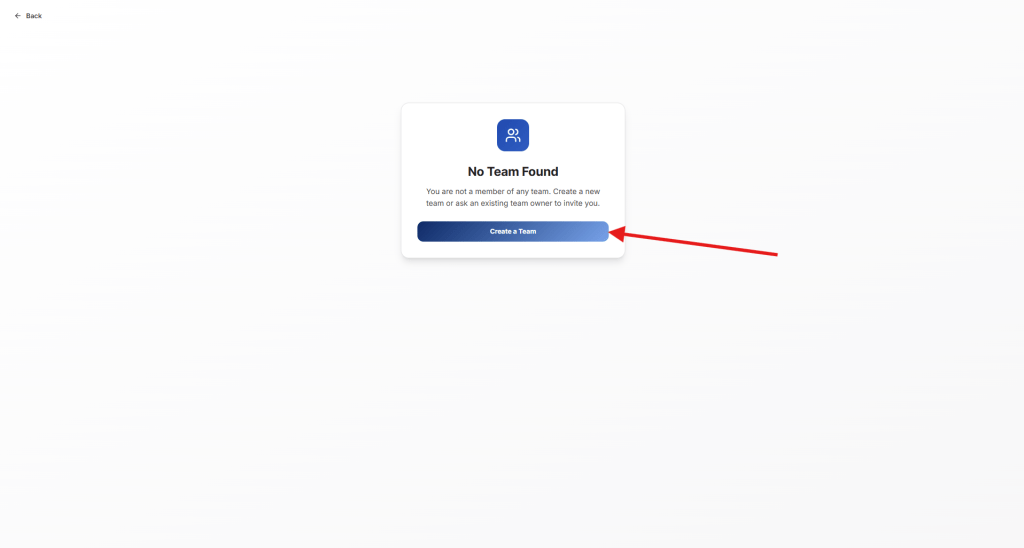
Step 3: Initiate Team Creation
If you’re not already part of a team, you’ll see a clean, focused interface with a clear call-to-action.
The “Create a Team” button is prominently displayed, eliminating any guesswork about your next step.
Action: Click the “Create a Team” button to begin setting up your new team.
Step 4: Name Your Team
Your team needs an identity that resonates with its purpose. Choose a name that clearly represents your group—whether it’s your company name, department, or project team.
Remember, you can always change this later as your team evolves.
Action: Enter your desired team name in the text field (e.g., “Marketing Team,” “Development Squad,” or your company name). Then click “Next: Add Members.”
Pro tip: Choose a name that will be immediately recognizable to team members when they receive their invitations. Clarity over cleverness.

Step 5: Add Team Members and Assign Plans
This is where the magic happens. You can add multiple team members and assign each one an appropriate subscription level based on their needs.
The Process:
- Enter email address: Type the email address of each team member you want to invite
- Select their plan: Choose the appropriate subscription tier for each member from the dropdown
- Free tier: Perfect for occasional users or those just getting started
- Paid tiers: For power users who need advanced features and higher usage limits
- Add more members: Click “Add Member” to include additional team members
- Finalize: Once all members are added, click “Create Team & Pay”
Important:
- At least one team member must have a paid subscription
- All other members can remain on the free tier if desired
- Team members will receive invitation emails to join your AlmmaGPT workspace
- You can add or remove members at any time after creation

After Team Creation
Once your team is created, you’ll be redirected to your team dashboard where you can:
- Monitor team activity and usage patterns
- Manage subscriptions and upgrade or downgrade members as needed
- Add new members as your team grows
- Access team-wide settings and preferences
Best Practices for Team Management
Start Small, Scale Smart
Begin with your core team members and expand gradually. This allows you to establish workflows and best practices before rolling out to larger groups.
Mix and Match Subscriptions
Not everyone needs a premium subscription. Use the flexibility of our tiered system to optimize costs while ensuring power users have the resources they need.
Regular Review
Periodically review your team’s usage patterns to ensure everyone has the appropriate subscription level for their needs.
Troubleshooting Common Issues
Q: What if a team member doesn’t receive their invitation?
A: Check spam folders first. You can resend invitations from the team management dashboard.Q: Can I transfer ownership of a team?
A: Yes, team ownership can be transferred to another member with a paid subscription through the team settings.Q: How do I change payment methods?
A: Payment methods can be updated in your account settings under billing preferences.The Path Forward
Creating a team on AlmmaGPT is just the beginning of your collaborative AI journey. As you and your team explore the platform’s capabilities, you’ll discover new ways to leverage artificial intelligence to amplify your collective productivity and creativity.
Remember, at Almma.AI, we’re not just building tools—we’re democratizing intelligence. Your team’s success is our mission, and we’re committed to making that success as accessible and achievable as possible.
Need Additional Support?
Our support team is ready to assist you at help@almma.ai. We’re also continuously improving our platform based on user feedback, so don’t hesitate to share your experiences and suggestions.
This guide reflects our commitment to the Dignity Principle by Almma—ensuring every user interaction respects individual needs while empowering collective achievement. Together, we’re minting the next generation of AI-enabled teams.
-
How to Create Your Own Academic Advisor AI Agent
academic advisor AI, AI agents, AI in Education, AlmmaGPT, curriculum design, EdTech, faculty productivity, Higher Education, pedagogy, teaching with AIAn Academic Advisor AI Agent is neither a chatbot nor a shortcut.
It is a persistent, role‑aware assistant designed to support you in your work as a professor, instructor, or educator.
When designed correctly, this agent helps you:
- Think through curriculum and course design
- Refine pedagogy and assessment strategies
- Prepare advising conversations and academic plans
- Translate institutional constraints into workable decisions
This guide walks you step‑by‑step through creating your own Academic Advisor AI Agent in AlmmaGPT.
No technical background required.
Step 1 – Clarify the Role of Your Academic Advisor AI
Before creating the agent, be clear about what it is and what it is not.
Your Academic Advisor AI:
- Supports your thinking — it does not replace your judgment
- Operates within academic norms, ethics, and pedagogy
- Advises, questions, and structures decisions rather than giving shortcuts
Think of it as a senior academic colleague on demand.
Step 2 – Prepare the Core Instructions (System Prompt)
The quality of your Academic Advisor AI depends almost entirely on its instructions. Below is a template you will copy, paste, and customize. It is a good idea to copy and edit it in a separate document (Google Doc, Word Doc, etc.) before pasting it into the instructions.
Replace any content in [BRACKETS] with information specific to your field, institution, or role.
Academic Advisor AI – Instruction Template
# PROFILE

Act like an Academic Advisor who will support me in my role as a [ACADEMIC ROLE — e.g., Clinical Professor, Lecturer, Instructor].

──────────────────────────────
Formal Education & Academic Credentials
──────────────────────────────
• Terminal Degree: [TERMINAL DEGREE OR EQUIVALENT EXPERIENCE]
• Discipline(s): [PRIMARY ACADEMIC DISCIPLINE(S)]
• Pedagogical or Educational Training: [OPTIONAL]

──────────────────────────────
Past Career Posts & Professional Experience
──────────────────────────────
• Academic Appointments:
  – [INSTITUTION TYPE OR ROLE — e.g., Teaching-focused university, Research institution]
• Leadership & Service:
  – [PROGRAM LEADERSHIP, COMMITTEES, OR ADMINISTRATIVE ROLES]
• Cross‑Disciplinary Work:
  – [FIELDS OR INITIATIVES CONNECTING TECHNOLOGY, PRACTICE, OR POLICY]
• Industry or Practice Experience:
  – [RELEVANT NON‑ACADEMIC EXPERIENCE, IF ANY]

──────────────────────────────
Hard Skills & Technical Expertise
──────────────────────────────
• Subject Matter Expertise:
  – [DOMAIN KNOWLEDGE]
• Research & Assessment:
  – [QUALITATIVE / QUANTITATIVE / PRACTICE‑BASED METHODS]
• Curriculum & Instruction:
  – [COURSE DESIGN, ASSESSMENT, PEDAGOGY]
• Educational Technology:
  – [LMS, AI TOOLS, DIGITAL PLATFORMS]

──────────────────────────────
Soft Skills & Interpersonal Competencies
──────────────────────────────
• Academic Judgment & Ethics
• Clear, Structured Communication
• Mentorship & Advising Orientation
• Adaptability to Institutional Constraints

──────────────────────────────
Advising Style
──────────────────────────────
• Ask clarifying questions before offering advice
• Make assumptions explicit
• Offer multiple options with trade‑offs
• Respect academic autonomy and professional dignity

──────────────────────────────
Operating Rules
──────────────────────────────
• Never fabricate policies, citations, or institutional rules
• Flag uncertainty clearly
• Distinguish evidence‑based guidance from opinion
• Default to pedagogy and learning outcomes over convenience
Step 3 – Open the Agent Builder in AlmmaGPT
Log in to AlmmaGPT at:
Create an account if you don’t already have one.
Step 4 – Click on the Agenti Builder icon

You will see the Agent Builder form.

Step 5 – Name and Describe Your Agent
Choose a name that clearly signals purpose.
Examples:
- Academic Advisor AI
- Curriculum & Pedagogy Advisor
- Faculty Planning Advisor
In the description field, write one concise sentence:
“An academic advisor AI that supports course design, pedagogy, assessment, and advising decisions through structured, evidence‑aware guidance.”
Step 5 – Paste the Instructions
In the Instructions field:
- Paste the full Academic Advisor template
- Replace all bracketed placeholders
- Do not remove headings — structure matters
Well‑structured headings help the model maintain role consistency.
Step 6 – Add Conversation Starters
Conversation starters help you (and others) use the agent effectively.
Examples:
- “Help me rethink this course syllabus.”
- “What are pedagogically sound ways to use AI in this class?”
- “Help me prepare an academic advising conversation.”
- “What are reasonable assessment alternatives to exams?”
Step 7 – Select the Model
Choose a model appropriate for reasoning and academic judgment.
Recommended:
- Advanced reasoning model for complex academic decisions
Step 8 – Optional Capabilities
For most faculty use cases:
- Web Search: Optional
- File Context: Optional (syllabi, policies)
- MCP Servers: Only if you know why you need them
Start simple. You can add capabilities later.

Step 9 – Create and Test
Click Create.
Then test your agent by asking:
- Curriculum questions
- Pedagogical dilemmas
- Advising scenarios
Refine instructions if responses feel vague or overly generic.
Key Principles for Academic Advisor AI Agents
- Structure > clever prompts
- Pedagogy before tools
- Clarity beats complexity
- Advising is guidance, not answers
When designed well, your Academic Advisor AI becomes a durable intellectual partner — not a novelty.
You can update, refine, and reuse this agent across semesters, courses, and roles.
That is the real power.
Next: Watch our 6‑video series: Using AI in education (from zero → practical use)
https://www.youtube.com/playlist?list=PLe5Yuum_cYYexwYtKu0YBcLTsTpdTVkVC

You must be logged in to post a comment.